This AI design skill refuses to look AI-generated.
The catch? It grades itself
Hallmark is a Claude Code skill that refuses to look AI-generated, and its own eval shows lint fails dropping to zero. The catch is who's doing the grading.
- Claim
- AI design that isn't slop?
- Catch
- GRADED BY ITSELF
- Verdict
- Guardrails, not taste
Hallmark, a design skill from Together AI, was #2 on GitHub's daily Trending list on October 26, 2026, with 33,620 stars and 1,359 of them that day. Its README says it "refuses to look AI-generated." It works with Claude Code, Codex, Cursor and OpenCode, and installs with npx skills add nutlope/hallmark -g. We read the README, the eval write-up and the roadmap.
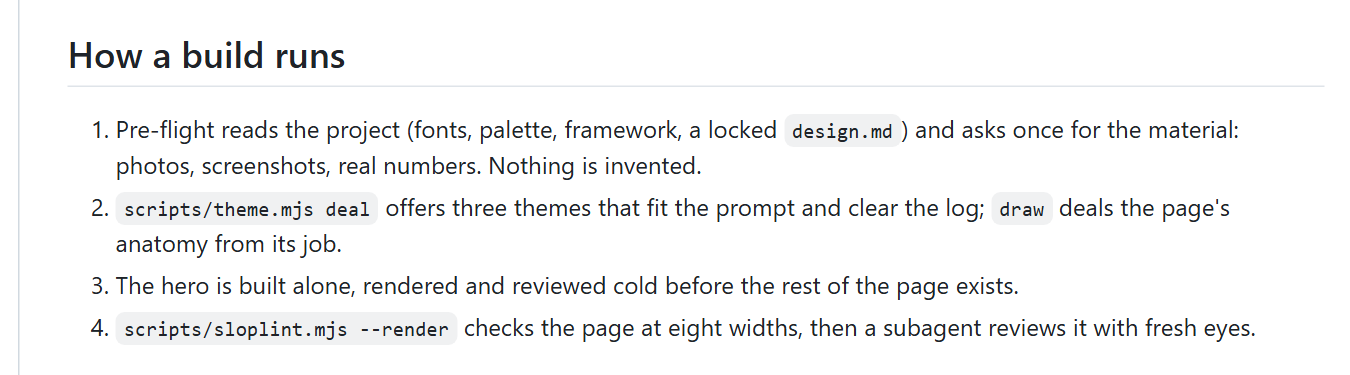
How a build runs
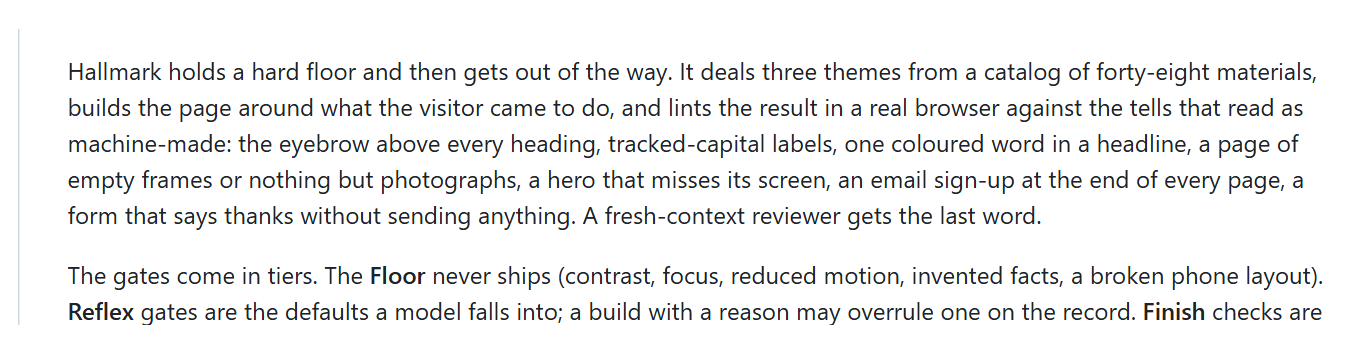
Ask Hallmark for a page and it doesn't write everything at once. Per the README, it deals three themes from a catalog of 48, builds the hero section alone and reviews it before the rest of the page exists, then runs its own linter, sloplint, at eight screen widths. Finally, a subagent with fresh context reviews the result.
The tells it hunts
The linter targets patterns that make a page read as machine-made. A few from the README's list:
- an eyebrow label above every heading
- tracked-out capital labels
- one coloured word in a headline
- an email sign-up at the end of every page
- a form that says thanks without sending anything
The last one is more than style. A form that pretends to work is a bug.
The test
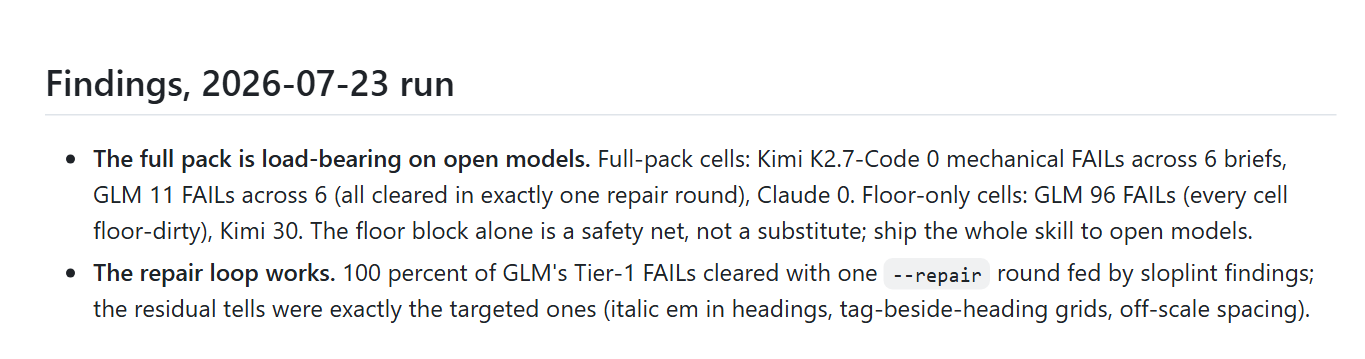
The project ran its own eval, with findings dated July 23, 2026. Given only Hallmark's basic "floor" rules as a prompt, models still failed the linter often. With the full skill, the fail counts dropped sharply:
| Setup | Lint fails |
|---|---|
| Floor rules only, GLM | 96 |
| Floor rules only, Kimi | 30 |
| Full skill, Claude and Kimi K2.7-Code | 0 across 6 briefs |
| Full skill, GLM | 11, all cleared after one repair round |
One more result we liked: on the brief built to tempt models into inventing metrics, none did.
The catch
Those fail counts come from Hallmark's own linter, run on Hallmark's own briefs, and the eval README says the bare-prompt tier is now kept as an archive. Build time and token cost aren't measured yet: "Measure a build" is still on the roadmap. The README also notes the skill may not trigger on its own, so name it in your prompt.
And the tells keep moving. The roadmap now says cream or off-white paper, pill-shaped buttons and the hairline broadsheet look read as generated. This website and our videos sit on cream paper, so we're taking that one personally.
Verdict
Strict guardrails, not taste in a box. If your agent keeps producing the same generic landing page, Hallmark's checks will catch a lot of it. Whether the result is actually good is still your call.
SOURCES
- Nutlope/hallmark README, eval/README.md ("Findings, 2026-07-23 run") and ROADMAP.md (github.com/Nutlope/hallmark), MIT license; stars via the GitHub API, October 26, 2026.
- GitHub Trending, daily view, October 26, 2026 (1,359 stars today).
Not affiliated with Together AI or Hallmark. Educational content, not design or business advice.


